Rebuilding a company's documentation as a product, and what the job becomes when you do it as a team of one.
Executive Summary
Over six months, Exchange Solutions' external documentation moved from a PDF-by-email distribution model across four disconnected tools to a single, versioned docs-as-code site: feature descriptions, an API reference, data feeds, console guides, and dated release notes, all kept current because staying current is built into how they're made. Done by one technical writer, the project turned on three reusable ideas: establish the source of truth before migrating, enforce structure with reusable components, and ground AI-assisted writing in extracted source code so the model becomes an auditor rather than a fabricator, producing a gap ledger of where the code and the docs disagree. The result reframes documentation from a byproduct a company exports into a product surface, and ultimately a feedback channel back into the product itself.
A client needs a piece of your documentation. Here is how they used to get it.
Somewhere inside the company, a stakeholder opens the relevant guide and exports it to PDF (or, if it's an API reference, copies out the raw JSON), attaches the file to an email, and sends it off. The client receives a document frozen at the moment of export, disconnected from the source that produced it, already beginning to drift out of date. Multiply that by every client, every product, every request. That was the distribution model I walked into as the newly hired Technical Writer, and the only technical writer, at Exchange Solutions.
It worked, in the sense that a thing that happens every day is working. But it raised a question I couldn't put down: why was our documentation something we sent, rather than somewhere clients could go?
The state of things
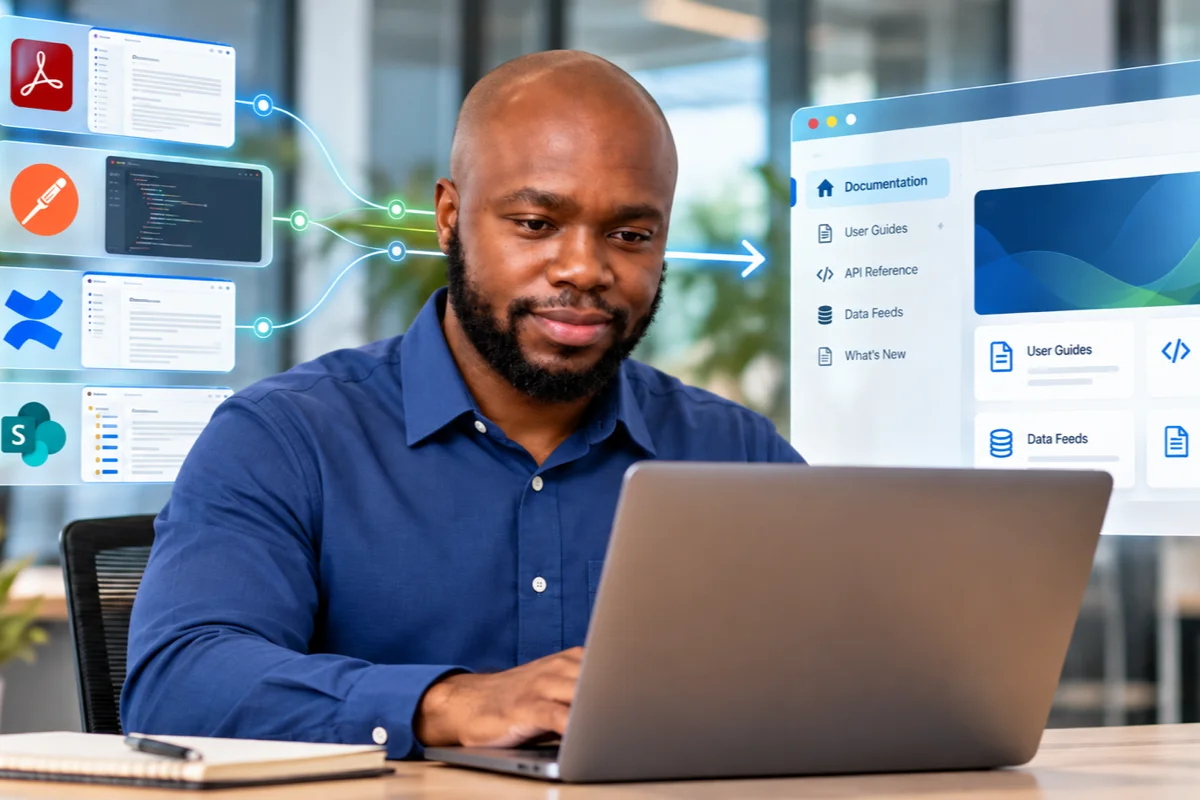
Before I could answer that, I had to live inside the existing setup, so for the first few weeks I did what the role asked. I contributed console user guides through RoboHelp. I maintained the API reference as a Postman collection. I wrote up data feeds in Confluence and SharePoint, and produced user-friendly release notes in Confluence. Four tools, four content models, four places a reader, internal or external, might have to look. None of them talked to each other, and none of them faced the client directly. Every external delivery required a human to act as a manual export layer.
Contributing inside that system taught me its shape faster than any audit could have. But I also stepped outside it. I looked at how the documentation teams I admired, the ones developers actually cite, presented their work, and the gap was not one of writing quality. It was architecture. The best docs weren't a collection of files; they were a single, versioned, browsable product. Ours were a filing cabinet that occasionally got photocopied.
The decision
So I proposed the obvious thing, which is often the hard thing. Unify every external-facing document into one repository, published through Docusaurus and maintained as docs-as-code, living in version control, next to the products it describes, updated through the same discipline as the software itself.
The point was never the tool. Docusaurus is a means. The point was a change in category. Documentation would stop being a byproduct we exported at the end of a cycle and start being a product surface with its own front door: one place clients could go, that stayed current because staying current was now built into how it was made.
Getting there was the work of the next several months. Here's how it went.
Building the machinery
From the outside, migration looks like moving furniture: pick the docs up from the old system, set them down in the new one. It wasn't. Each source stream had its own format, its own authoritative version, and its own reasons the content couldn't simply be pasted across. Before I moved a single page, I had to settle two questions that applied to everything, and one that had to be answered stream by stream.
The first cross-cutting decision was a writing standard. I adopted the Google developer documentation style guide, not because it's the only good one, but because a single, externally maintained standard gives a solo writer a rule to point to instead of relitigating voice on every page. The second was spelling, which was less obvious than it sounds. Our clients sit on both sides of the Canada-US border, so the docs use both American and Canadian English depending on context; where a page forced a single choice, American English took precedence. A small decision, but the kind that produces inconsistency forever if you never actually make it.
The stream-by-stream question was source of truth. Before rewriting anything, I identified the authoritative version of each content type, the copy clients were actually relying on, so that the migration corrected format without quietly changing meaning.
For the console guides, that source was RoboHelp. Migrating meant rewriting each guide in Markdown while preserving the things that carry the real information: screenshots, inline notes, the procedural steps. I ran the rewrites through an LLM constrained by the style guide, so the same pass that modernized the prose also normalized it.
For the API reference, the source was the ES Loyalty API suite's Postman collection, the same collection already shared with clients. Exporting its JSON gave me a structured starting point, which I used to generate the reference as MDX built on reusable components, so every endpoint renders the same way: path parameters, headers, request body, response, errors, worked examples. Two pages side by side make the point: Start Session and Issue Ad Hoc Reward share an identical skeleton. That is the payoff of the reusable-component approach: a new endpoint inherits the structure instead of reinventing it.
For the feeds, the authoritative content lived in the Confluence and SharePoint repositories the team had maintained for both operational and data-warehouse feeds. That data was the most accurate representation of what clients integrate against, so it became the basis for the migrated feed specifications: structured field tables paired with format examples.
Release notes followed the same logic. They already existed in Confluence, so the migration moved them onto the site's What's New feed, but this was the one stream where I changed the format on purpose. Instead of a raw changelog, each entry describes what shipped in terms of the value it delivers to specific stakeholders (members, program owners, support teams), so a release note reads as something a client can act on rather than a list of tickets closed.
One stream didn't fit this pattern at all, because it wasn't a reformat. It was net-new external content built from nothing. That's the feature-descriptions project, and it's the subject of the next section.
The reusable takeaway is the ordering. Source of truth first, so you know you're preserving the right thing. Writing standard second, so every page converges on one voice. The LLM sits inside those two rails as the engine that does the rewriting at a scale a single writer couldn't reach by hand, but the rails are what keep the scale trustworthy.
Describing seventy features from the source up
The console guides, API reference, and feeds all had one thing in common: an authoritative version already existed somewhere. The feature descriptions did not. There was no external-facing catalogue of what ES Loyalty actually does, feature by feature, capability by capability. What existed lived in Confluence, written for internal readers and dense with the things you can't publish: client names, JIRA tickets, PRD links. This wasn't a migration. It was building a reference library from nothing, for roughly seventy features across six domains (admin and platform, engagement, integrations, members, program, and rewards), each with its own sub-features and capabilities.
The obvious approach has a quiet flaw. You read the internal docs, strip the sensitive parts, and rewrite for clients. But internal docs drift. They describe what a feature was supposed to do when someone wrote them down, not necessarily what it does now. Documenting from those would launder yesterday's assumptions into today's client-facing reference.
So I documented from the source instead: the actual source, the code.
I set up a project and gave it the context a new technical writer would need to be trustworthy: the company glossary, the user personas, and the existing feature sheet. Then I wrote a prompt that, for each feature, analyzed the relevant part of the code repository, pulled out what the feature actually did, and used that extracted behavior as the basis for the description. The writing was derived from the system, not from someone's earlier account of the system.
The part I'd point any other writer to is what the prompt did on the side. As it wrote each description, it also produced an internal section flagging every place where the code and the existing documentation disagreed: a gap ledger. Where the feature sheet claimed a capability the code didn't support, that surfaced. Where the code did something the docs never mentioned, that surfaced too. The most common objection to AI-written documentation is that models invent things; here the model's job was the opposite. Grounded in extracted code, it became an auditor. The same pass that produced the client-facing page produced a list of discrepancies for the product team to resolve.
That reframes what the documentation is for. A feature reference written this way isn't just an output; it's a periodic reconciliation between what the company believes it built and what it actually shipped. The published pages are the visible half: each one an overview, a business-value statement, a worked example, and a table of capabilities with their configurations and constraints. The gap ledger is the invisible half, and arguably the more valuable one, because it turns every documentation cycle into a lightweight product audit.
None of this removed the human. Net-new external content, assembled partly from code, went through multiple review and spellcheck passes before it went live, both to catch the model and to make the final call on what was safe and accurate to publish. But the shape of the work changed. I wasn't transcribing a product I'd been told about. I was describing a product I'd read, and reporting back on the places where the telling and the building had come apart.
Measuring what the docs do
Publishing the site is where most documentation projects stop and where mine started to get interesting. I added Google Analytics to the docs, and the first use of it is the obvious one: find the pages with high bounce rates and work out why people leave. That's table-stakes technical writing.
The question I'm actually chasing is bigger. A documentation site instrumented like a product generates the same kind of signal a product does: which features people look up most, where they drop off mid-task, which endpoints and feeds draw the most traffic, what people search for and don't find. That isn't a cleanup list. It's a read on what clients are trying to do and where the product, or its documentation, is making that hard. Used that way, analytics stops being a hygiene tool for the docs and becomes a feedback channel back into the product: the same instinct behind the gap ledger, pointed at readers instead of code.
I'm early on this. But the direction is set: the documentation shouldn't just describe the product, it should report on how it's used. That's the next thing I'm building, and probably the next thing I'll write about.
What the job is now
Six months ago, a client who needed documentation got a PDF in their inbox. Now they get a URL: a single, versioned site covering feature descriptions, an API reference, feeds, console guides, and dated release notes, kept current because staying current is built into how it's made.
I did that as a team of one, and I want to be careful about the lesson in it. The point isn't that one writer can now do the work of several through sheer tooling. It's that the work itself changed shape. A documentation team of one used to mean triage: deciding what you couldn't get to. With the right machinery around you, it can mean something closer to leverage: source-grounded writing, structure enforced by reusable components, a product audit falling out of the documentation process, usage data flowing back the other way.
I don't think that makes the technical writer smaller. I think it makes the role more like what it always claimed to be: the place where a product gets explained to the people who have to trust it. What I'm less sure about is where the new edges are. That's the part I'd like to hear the rest of you argue about.
The platform behind the documentation
Exchange Solutions builds and operates ES Loyalty — the API reference, feeds, and feature library in this article all document a working enterprise loyalty system.
Frequently Asked Questions About ES Loyalty
Find answers to common questions about our platform and solutions